 Design
 App Development
 Web Engineering
 AI Services
 Cloud
 Staffing
 Startups
 Health / Fitness
 Education
 Social
 Nonprofit
 Fintech
 Construction
 Logistics
 Government
 Travel/Hospitality
 HR Software
 About Simpalm
 Our News
 Client Testimonials
 Careers
 Our Blog
 Awards
 Resources
 Information

Key Takeaways
- Most existing software can add AI without a full rebuild by using APIs, sidecar assistants, or incremental AI features around the existing system.
- The right AI integration pattern depends on the existing system, including its technology, compliance requirements, team capabilities, and risk tolerance.
- AI integration costs typically depend on whether the project involves a basic API feature, copilot, or complex agentic automation.
- AI features in regulated software must extend existing compliance controls to cover how third-party AI systems send, process, store, and log sensitive data.
- Successful AI retrofits require production guardrails such as prompt-injection protection, usage limits, audit logs, controlled AI permissions, and testing with realistic data.
_________________________________________________________________________________________
Most software leaders who bring up “adding AI” to their product are not actually asking whether AI is a good idea. They already know it is. What they are really asking, often without saying it directly, is whether they need to blow up years of stable business logic to get there.
That fear is not irrational. A full platform rebuild is expensive, slow, and prone to losing the quiet, undocumented rules that make a legacy system actually work. But it is also, in most cases, the wrong instinct. Gartner predicts that 40 percent of enterprise applications will be integrated with task-specific AI agents by the end of 2026, up from less than 5 percent in 2025. Almost none of that growth is happening through ground-up rewrites. It is happening through AI layered onto systems that already run a business.
At the same time, McKinsey’s State of AI research finds that 88 percent of organizations now use AI in at least one business function, yet only a small fraction qualify as high performers capturing meaningful financial return. The gap between those two numbers is not a gap in ambition. It is an execution gap, and a lot of it comes down to how AI actually gets connected to the software teams already depend on.
So the real question for most businesses is not “should we use AI?” It is “where does AI plug into what we already have, and how do we make that decision without guessing?” This guide walks through exactly that: the integration patterns available, a decision framework for choosing between them, what each option actually costs, and how to stay compliant when the system you are modifying already handles regulated data.
Why Adding AI May Not Require a Full Software Rebuild?
There is a common instinct among engineering leaders that if you want to do something as fundamentally new as AI, you need a fundamentally new system to hold it. It feels clean. It feels like a fresh start instead of duct tape on an old frame.
In practice, that instinct usually backfires. A rebuild resets years of edge case handling that nobody wrote down because it was never supposed to need writing down. It extends timelines from weeks to quarters or years. It multiplies cost, since the team is now maintaining two systems in parallel during migration instead of one. And it introduces a new category of risk: a rebuilt system that has not yet been battle-tested by real customer behavior, deployed at the exact moment a company is also trying to prove out a new AI capability.
Editor’s note: Treat a full rebuild as a last resort, not a default starting point. The businesses that get AI into production fastest are seldom the ones that cleared the table first. They are the ones that found the smallest, safest point of contact between a new AI capability and the system that already works.
That said, a rebuild is sometimes the right call. It is worth being honest about when.
- No stable interfaces exist. If the current system has no APIs, no clean data access layer, and no way to expose functionality without touching tightly coupled legacy code, layering AI on top may be more expensive than starting over.
- Permissions cannot be enforced. If the system cannot reliably control who sees what data, adding an AI feature that summarizes, retrieves, or acts on that data will amplify an existing security gap rather than create a new one.
- The data model actively works against the use case. Some legacy schemas were built for a business that no longer exists. If the data an AI feature needs simply is not captured in a usable form, no amount of clever integration will fix that.
- The team lacks any path to iterate safely. If every deployment is a multi-week manual process with no staging environment, adding AI (which requires fast iteration to tune well) will be miserable regardless of pattern.
If none of those apply, and for most established products none of them do, a rebuild is solving a problem the business does not actually have.
Also Read | How to Implement AI into an App leveraging OpenAI APIs?
Three Ways to Layer AI Onto an Existing Product
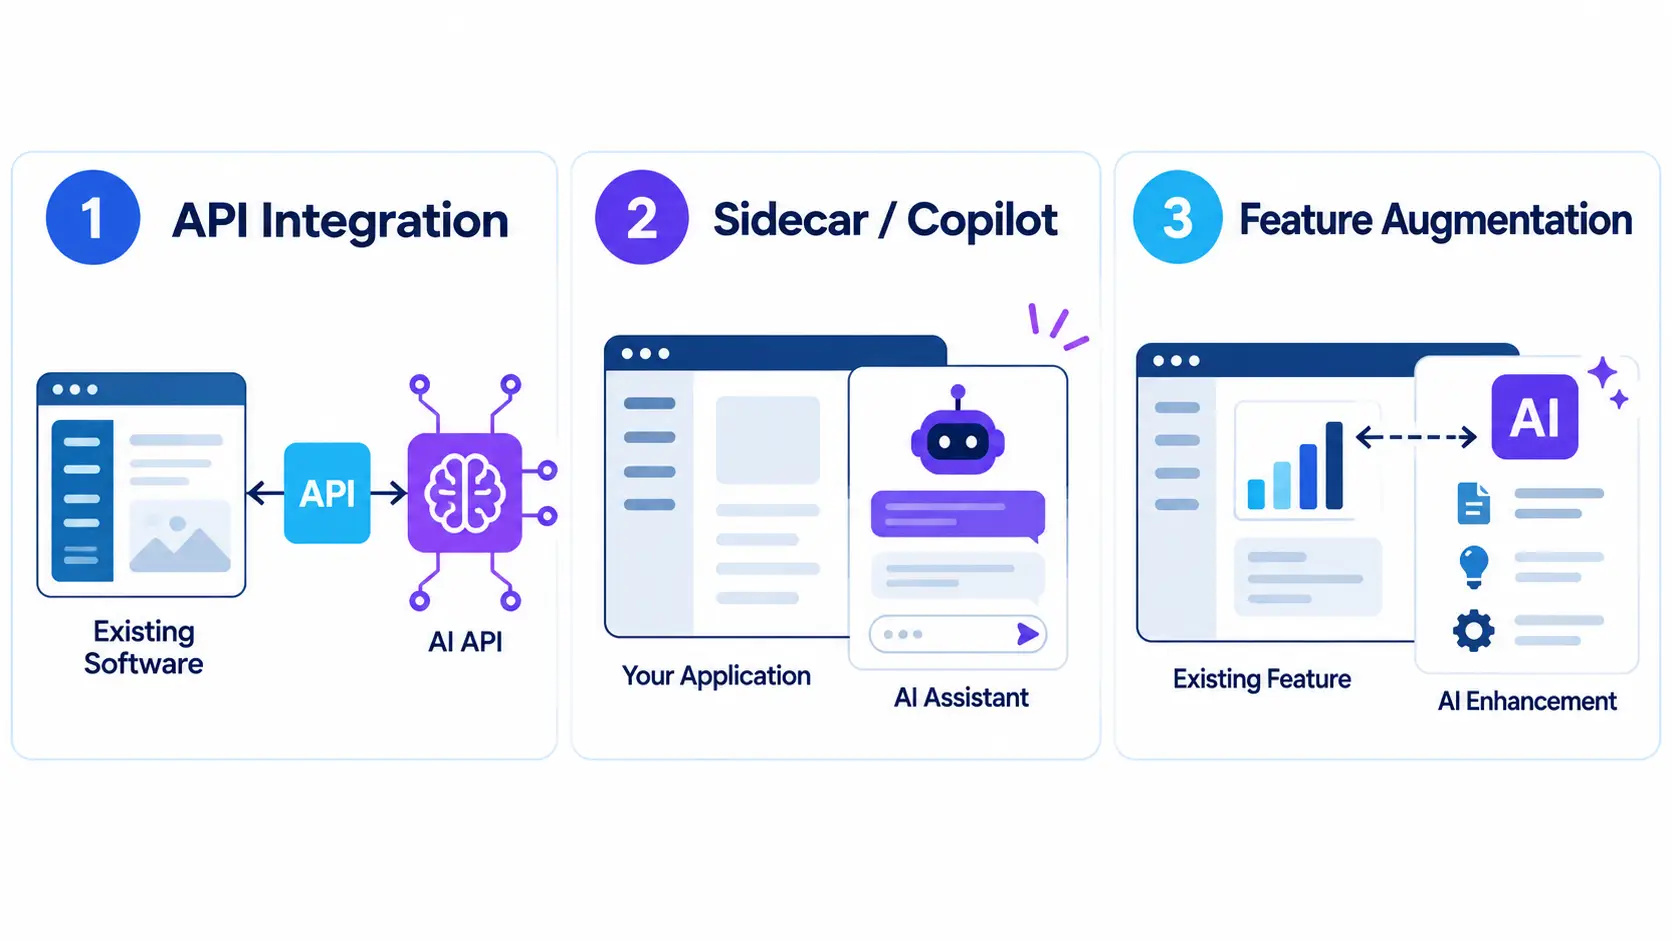
Once a full rebuild is off the table, there are three practical patterns for adding AI capability to software that already exists. Each has a different risk profile, a different implementation cost, and a different ceiling on what it can do.
- API-first integration: This pattern calls an external AI model, typically a large language model or a specialized machine learning API, directly from existing backend code, without changing the surrounding architecture. A support ticketing system might add a call to an AI API that summarizes a long thread before a human agent reads it. A logistics platform might send incoming shipment documents to an extraction API instead of building an OCR pipeline from scratch. This is the fastest pattern to ship and the easiest to roll back, since the AI call sits at the edge of the system rather than inside its core logic.
- Sidecar or copilot pattern: Here, AI runs as an assistant layered next to the primary product experience rather than embedded inside it. Think of how Notion AI sits alongside a document without controlling the document’s core editing logic, or how GitHub Copilot suggests code inline without ever committing anything on its own. A sidecar pattern works well when the goal is to accelerate a human’s existing workflow rather than automate a decision outright, and it keeps a clear boundary between “AI suggested this” and “a human approved this.”
- Incremental feature augmentation: This pattern embeds AI directly into an existing feature to make it smarter, rather than adding a new, separate AI-labeled feature. Smart compose in an email client and predictive autofill in a form are both examples: the underlying feature already existed, and AI simply improved how it behaves. This pattern tends to have the lowest user-facing risk, since the feature fails gracefully back to its original, non-AI behavior if the model underperforms.
| AI Integration method | Typical Risk | Implementation Effort | Best For |
| API-first integration | Low to moderate | Low, days to a few weeks | Adding a discrete AI capability (summarization, extraction, classification) to an existing workflow |
| Sidecar or copilot | Moderate | Moderate, several weeks to a couple of months | Assisting a human-driven workflow without automating the final decision |
| Incremental augmentation | Low | Low to moderate | Improving an existing feature’s intelligence without introducing a new user-facing surface |
Which Integration Pattern Actually Fits Your System?
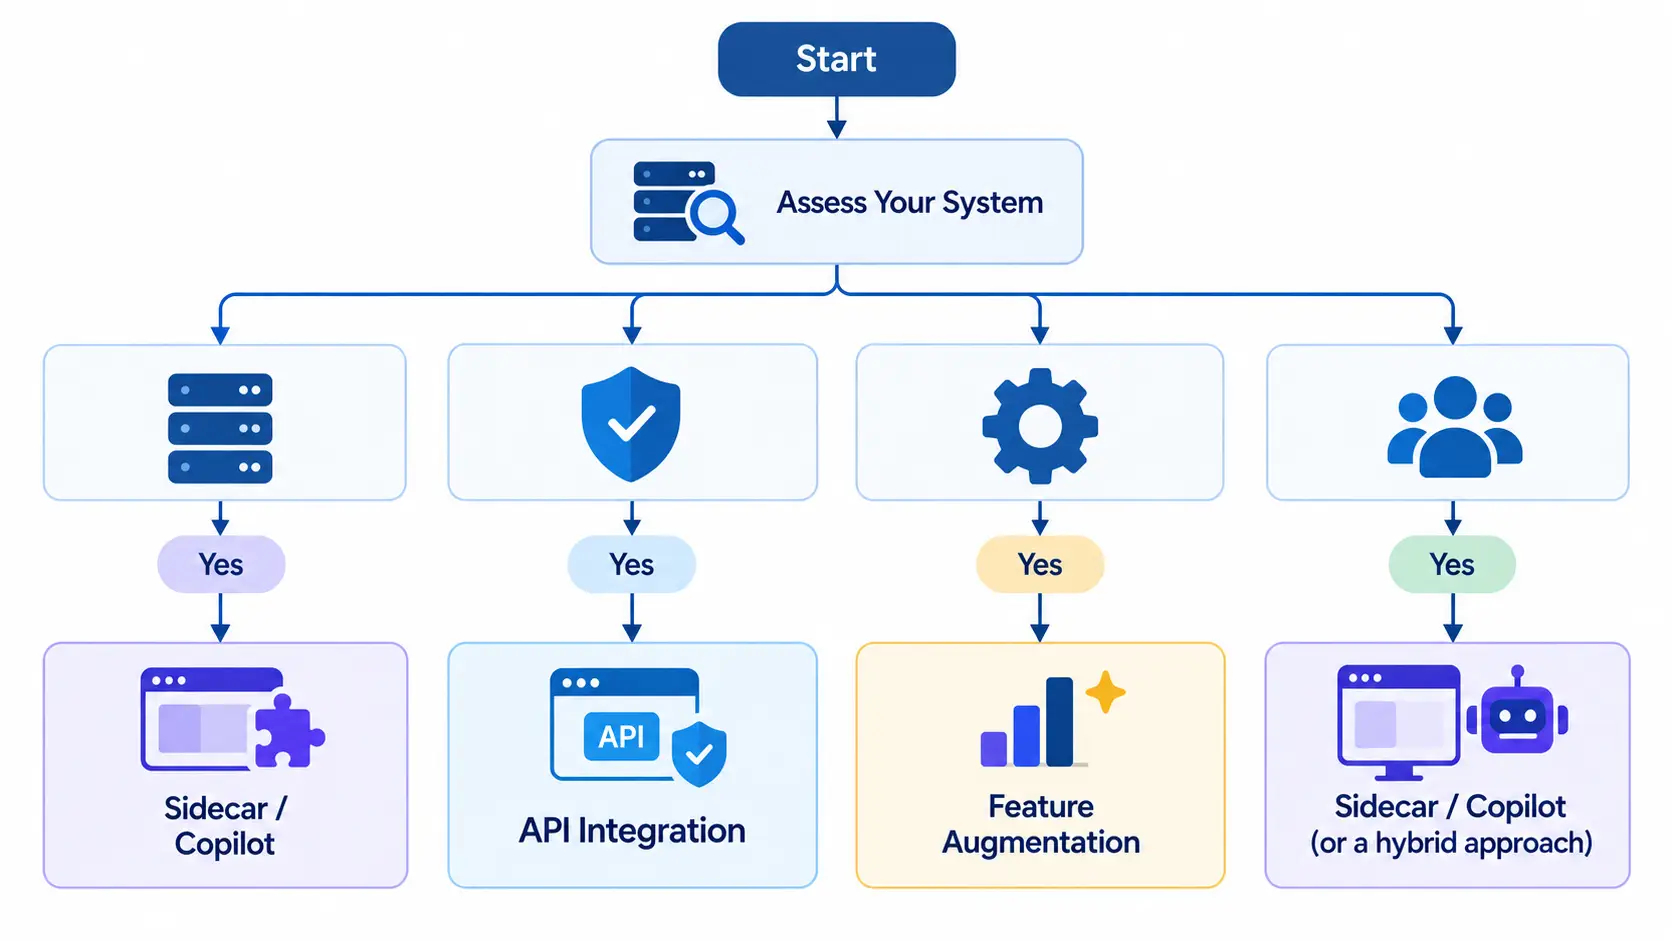
Knowing the three patterns exist is one thing. Choosing between them for a specific system is another, and this is usually where teams get stuck. The right pattern depends less on what AI can theoretically do and more on constraints already baked into the business.
| Situation | Recommended Starting Pattern | Why |
| Legacy backend in an older language (COBOL, classic ASP, older Java) with limited API surface | API-integration with Architectural Wrapper Pattern | Avoids touching fragile core logic; AI call happens in a new, isolated service layer |
| Heavy compliance load (healthcare, finance, government) | Sidecar or copilot, with human approval required | Keeps a human accountable for any action tied to regulated data, which most compliance frameworks require or strongly favor |
| Low risk tolerance for user-facing failure | Incremental augmentation | AI degrades gracefully into existing, proven feature behavior |
| High risk tolerance and clear automation ROI | API-first integration with a path toward agentic workflow orchestration | Sets up the architecture to expand from single AI calls into multi-step automation later |
| Existing workflow is already human-in-the-loop and slow | Sidecar or copilot | Directly targets the bottleneck (human review time) without removing human judgment |
Most teams should start in the left-most column of risk and complexity that still solves their actual problem, then expand. A business that begins with a narrow API-first integration for document summarization, for example, often finds it has built the connective tissue needed to later orchestrate a broader workflow using automation tools like n8n, without ever having committed to a rebuild.
Full Rebuild or AI Layer: How to Actually Decide?
Putting it plainly, the decision comes down to two questions asked in order.
- First, does the system have the basic technical hygiene (stable interfaces, enforceable permissions, usable data) to support any of the three patterns above? If yes, layering AI on top is almost always faster, cheaper, and lower risk than a rebuild.
- Second, if the answer is no, is the underlying gap something that can be fixed with a smaller, targeted modernization project rather than a full rewrite? Adding an API layer to a legacy system, for instance, is a much smaller project than replacing that system entirely, and it often solves the exact blocker that made AI integration look impossible in the first place.
A full rebuild only becomes the right answer when both of those paths are closed: the system cannot support AI as it stands, and the gap is too structural to patch. In practice, that combination is uncommon. Most businesses asking “do we need to rebuild to add AI” already have more of the foundation they need than they realize.
What It Actually Costs to Add AI to Existing Software?
Cost is where a lot of AI retrofitting conversations stall, mostly because the numbers thrown around in vendor pitches rarely map to a specific pattern or business size. Breaking cost down by integration tier makes the decision far more concrete.
| Model | Budget Tier | Mid Tier | Flagship Tier |
| OpenAI | $0.05 / $0.40 (GPT-5 nano) | $2 / $12 (GPT-5.6 Terra) | $5 / $30 (GPT-5.6 Sol) $10 / $50 (GPT-6 Astra) |
| Claude (Anthropic) | $1 / $5 (Haiku 4.5) | $2 / $10 (Sonnet 5) | $5 / $25 (Opus 5) $10 / $50 (Fable 5.1) |
| Gemini (Google) | $0.10 / $0.40 (Flash-Lite) | $1.50 / $7.50 (Flash) | $2 / $12 (3.1 Pro, ≤200K context) $4 / $18 beyond 200K |
| Cloud Cost (AWS, Azure, GCP) |
Using AI in your application also increases the cloud cost of your application, as the application needs to run more computation and API calls. | ||
The model price is only one part of the ongoing cost. Two other factors can significantly affect what you actually spend after the AI feature goes live:
- AI usage and inference: Model providers charge based on usage, typically through input and output tokens or other inference-based measures. As usage grows, these costs increase with traffic and can materially affect the cost of running high-volume AI features.
- Automation and agent platforms: If the integration moves beyond simple AI calls into multi-step agentic workflows, you may also need an automation or orchestration platform. These tools can add subscription or usage-based charges on top of development and infrastructure costs.
This means the cost of adding AI should be viewed as a combination of development, model usage, cloud infrastructure, and ongoing automation costs, rather than as a one-time integration expense.
Also Read | How Much Does It Cost to Build a Web App?
Staying Compliant When You’re Retrofitting AI Into Regulated Software

Adding AI to a system that already touches regulated data does not create a new compliance category from scratch. It extends the obligations that already exist to a new data flow, and that flow needs the same scrutiny as any other.
- HIPAA: If the system handles protected health information, any AI feature that processes, summarizes, or generates content from that data needs a signed business associate agreement with the AI vendor, encryption in transit and at rest for anything sent to the model, and an audit trail showing what data went where and when. A support-summarization feature that ingests patient messages, for example, has to treat the AI API call exactly like any other third-party data transfer under HIPAA, not as an internal utility
- PCI DSS: If any AI feature touches payment card data, even indirectly (for example, an AI agent that reads customer support tickets which sometimes contain pasted card numbers), that data needs to be scrubbed or tokenized before it reaches the model. Sending raw cardholder data to a third-party AI API, even briefly, can pull that vendor into PCI scope in ways most teams do not intend and do not want.
- GDPR: For any AI feature serving users in the EU, the retrofit needs a clear legal basis for processing personal data through the model, a documented data residency position (where does the data actually get processed, and does that location meet adequacy requirements), and a workable answer to the right to erasure. If a user’s data was used to fine-tune or cache responses in a way that is hard to unwind, that creates a real compliance gap that needs to be solved before launch, not after a request comes in.
Editor’s note: The single most common compliance mistake in AI retrofits is treating the AI vendor’s infrastructure as an extension of trusted internal systems. It is not. Every AI API call that touches regulated data is a third-party data flow, and it should go through the same vendor risk review as any other external integration.
Also Read | The Complete Guide for Mental Health App Development
Common Pitfalls When Retrofitting AI
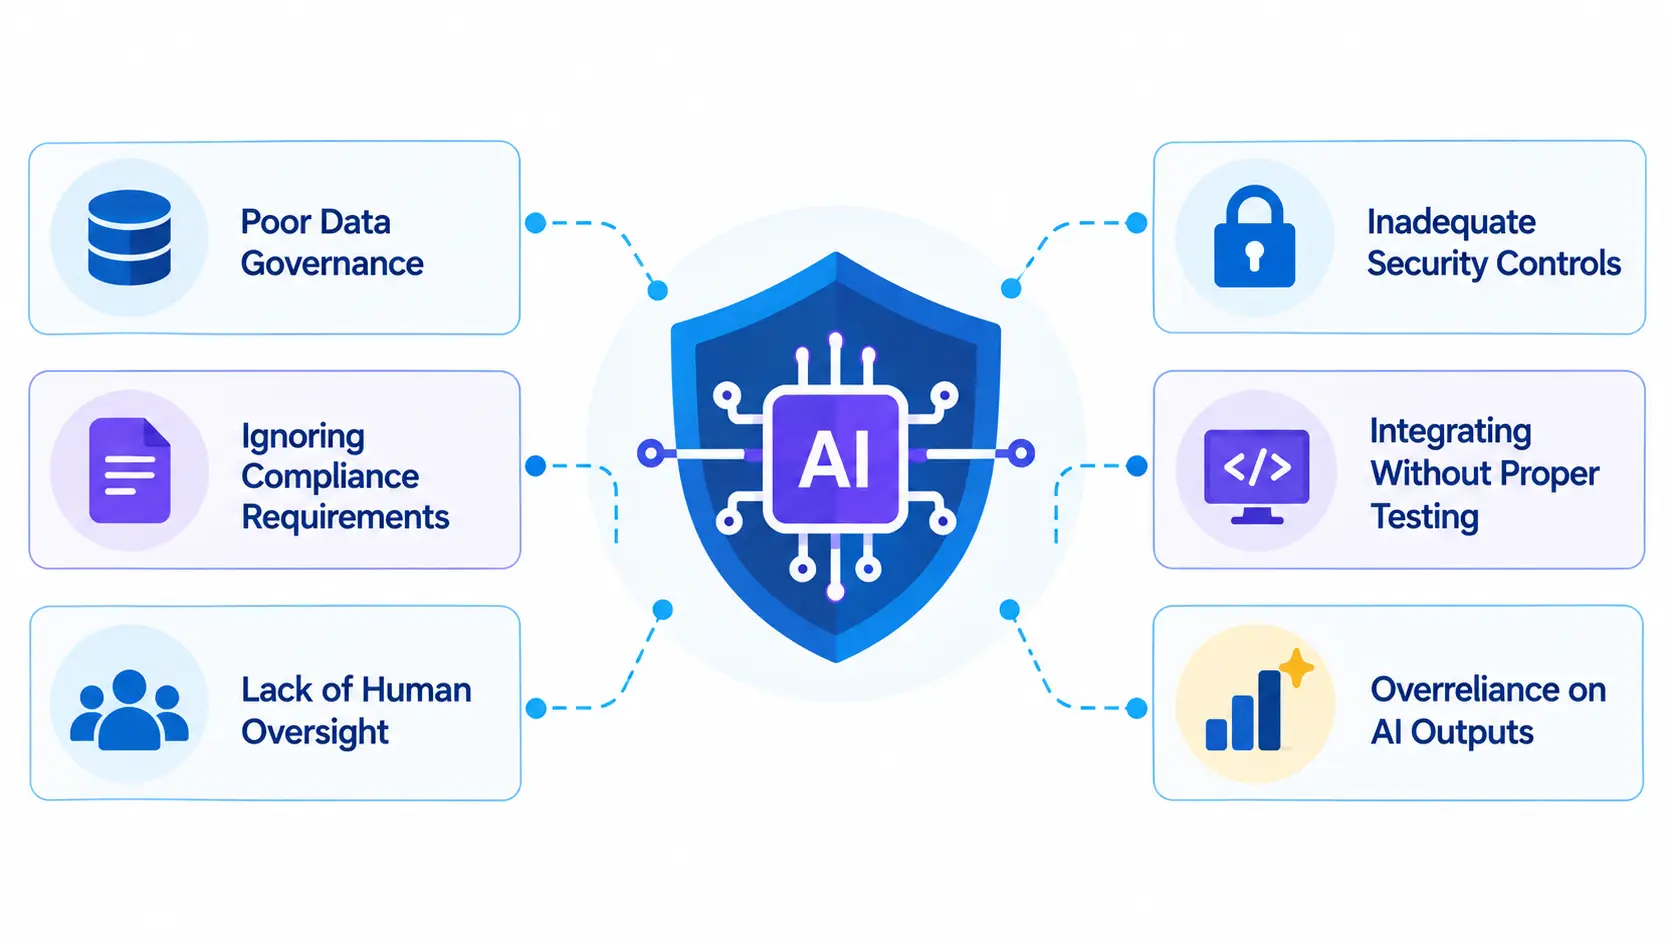
Even with the right pattern chosen and compliance mapped out, a handful of recurring problems trip up most AI retrofit projects. Each has a specific, addressable fix.
Challenge: Prompt injection risk.
When an AI feature processes user-generated content (a support ticket, an uploaded document, a chat message), a malicious or careless user can embed instructions inside that content designed to manipulate the model’s behavior.
Fix: Treat any content the model reads as untrusted input. Strip or neutralize instruction-like patterns before they reach the model, limit what actions the model can take autonomously based on that content, and log every AI decision so unusual behavior can be traced back to its source.
Challenge: Cost overrun from per-user token usage.
A feature that looked affordable in testing can become expensive fast once real users start generating volume, especially with features that process long documents or maintain long conversation histories.
Fix: Set hard usage caps per user or per account tier, cache repeated queries where possible, and monitor cost per active user weekly during the first months after launch rather than waiting for a monthly bill to reveal the trend.
Challenge: Coupling AI logic into core business logic.
It is tempting to let an AI call directly influence business-critical decisions (pricing, eligibility, approval), which makes the system harder to debug, audit, and roll back if the model behaves unexpectedly.
Fix: Keep AI output as a recommendation or input to a decision, not the decision itself, unless the use case has been specifically validated for full automation. Maintain a clear, logged boundary between what the model suggested and what the system actually did.
Challenge: Treating pilot demos as production-ready.
A prompt that works well on ten curated test cases often breaks down across the messy diversity of real production data, and teams sometimes ship straight from a successful demo without stress-testing edge cases.
Fix: Build a test set from real, anonymized production data before launch, not synthetic examples, and run it against the AI feature regularly as the underlying model or prompt changes.
Data privacy pitfalls follow a similar pattern to the compliance-specific rules covered above. Simpalm’s guide to COPPA-compliant app development is a useful reference for how third-party AI and analytics SDKs can quietly expand a company’s compliance liability beyond what the core product team intended, a risk that applies well beyond apps serving children.
Final Thoughts
The businesses getting real value from AI in 2026 are not the ones that treated it as a platform bet requiring a ground-up rebuild. They are the ones that treated it as incremental capability-building: a summarization call here, a copilot there, a workflow automated once the underlying pattern was proven. That approach compounds. Each successful, narrow integration builds the architecture, the internal trust, and the operational muscle needed for the next one, without ever requiring the business to pause its roadmap for a year to rebuild something that was already working.
If your team is weighing where AI actually fits into a system you have already invested years into, Simpalm’s AI development team can help map the right integration pattern to your specific architecture, compliance requirements, and budget, without defaulting to a rebuild you probably do not need.
Frequently Asked Questions
Q1. Do I need to rewrite my legacy backend to use AI?
In most cases, no. If your legacy backend has any way to expose an API endpoint or a data access layer, even a limited one, an AI feature can typically be integrated at that boundary without touching the underlying legacy code. The exceptions are systems with no programmatic access at all or systems where permissions cannot be reliably enforced, both of which create risk independent of AI and are worth fixing regardless of whether AI is involved.
Q2. How long does a basic AI integration take?
A basic API-first integration, such as adding AI-powered summarization or classification to an existing workflow, typically takes two to six weeks from scoping to production, assuming the target system already has usable APIs. Timelines extend significantly if the team also needs to build API access to a legacy system first, or if the use case requires extensive prompt tuning against messy real-world data before it performs reliably.
Q3. Can AI safely write to my production database?
It can, but only with strict guardrails in place. Any AI feature that writes to production data should operate through the same validation, permission checks, and audit logging as a human user would, and ideally within a constrained set of allowed actions rather than open-ended database access. Most teams are better served starting with read-only or recommendation-only AI features and expanding to write access only after the feature has proven reliable over real usage.
Q4. How do I know if my use case needs a rewrite instead of a layer?
A rewrite becomes necessary when the current system has no stable way to expose data or functionality, cannot enforce who has access to what, or stores data in a form that simply does not support the use case no matter how it is queried. If none of those apply, which is true for most established software, a rewrite is very likely solving a problem that a targeted integration could solve faster and at a fraction of the cost.